11.2026
VECTORFORGE AI
A custom-built Java vector database and local Retrieval-Augmented Generation (RAG) engine featuring HNSW, KD-Tree, Brute Force search, real-time PCA visualization, and Ollama inference.
 Java
 Spring Boot
 React
 Ollama
Introduction
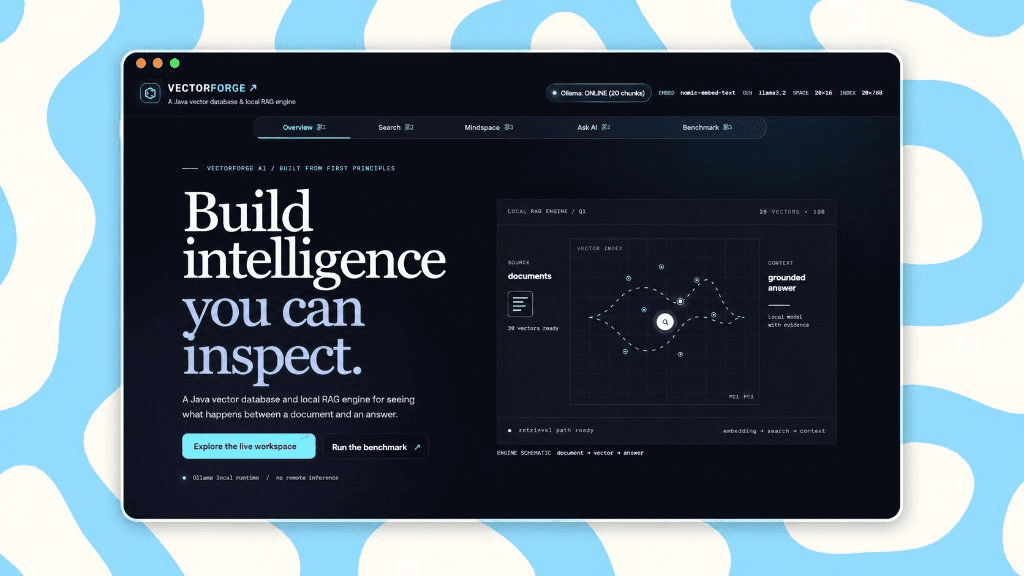
VECTORFORGE AI is an educational, production-grade vector database and local Retrieval-Augmented Generation (RAG) engine built completely from first principles in Java 21 and Spring Boot, paired with a responsive React 19 frontend.
Modern artificial intelligence systems rely heavily on commercial or hosted vector databases (such as Pinecone, Qdrant, or Milvus) to ground Large Language Models. However, to most developers, these databases remain opaque black boxes. VECTORFORGE AI deconstructs and demystifies the internals of vector storage, spatial indexing, distance metric calculations, high-dimensional dimensionality reduction, and local LLM orchestration—all runnable locally with zero external database dependencies.
Why I built it
While working with retrieval-augmented generation systems, I observed that many engineers treat vector retrieval as magic: text goes in, vectors come out, and answers appear. Trade-offs between exact nearest-neighbor search (O(N)) and approximate nearest-neighbor graphs (O(log N)) are rarely inspected directly.
I built VECTORFORGE AI to create a transparent, first-principles laboratory where developers can:
- Compare indexing algorithms side by side: Benchmark Hierarchical Navigable Small World (HNSW), KD-Tree, and Brute Force search on identical queries to observe real microsecond latency, nodes visited, and recall.
- Execute 100% private local RAG: Chunk real documents, generate 768-D embeddings using Ollama's
nomic-embed-text, retrieve cosine-ranked contexts via a custom HNSW index, and stream grounded answers fromllama3.2without leaking proprietary data to cloud APIs. - Visualize high-dimensional embeddings: Project high-dimensional vectors onto an interactive 2-D canvas in real time using a custom Principal Component Analysis (PCA) engine.
Core features
- Three search algorithms built from scratch:
- HNSW (Hierarchical Navigable Small World): Multi-layer proximity graph with heuristic neighbor selection (Malkov & Yashunin 2016), delivering sub-millisecond approximate search and high recall.
- KD-Tree: Space-partitioning binary tree with metric-specific bounding-box distance lower bounds for provably exact pruning.
- Brute Force: Exhaustive linear scan with bounded max-heaps serving as the mathematical ground truth.
- Three distance metrics: Full support for Cosine Distance, Euclidean Distance (
L2), and Manhattan Distance (L1), complete with axis-aligned bounding box lower bounds. - Full local RAG pipeline: Sliding-window chunking (250 words / 30-word overlap), real-time embedding via Ollama, cosine-distance context retrieval, strict prompt grounding, and Server-Sent Events (SSE) token streaming.
- Server-side PCA visualization: Custom linear algebra engine computing covariance matrices and cyclic Jacobi eigenvalue decompositions to project vectors onto a live 2-D scatter plot.
- Algorithmic benchmarking suite: Synthetic dataset generator evaluating build times, query latencies, nodes visited, and recall across dataset sizes from 20 to 50,000+ vectors.
- Unified single-artifact architecture: Precompiled React 19 + Vite frontend embedded directly into Spring Boot static resources, running out-of-the-box from a single executable JAR.
How it works
- Document ingestion & chunking: Ingested articles or text are segmented using a sliding window with configurable token overlap to preserve sentence boundaries.
- Dense vector embedding: Chunks are sent to the local Ollama instance (
nomic-embed-text), producing 768-dimensional dense vectors stored in a dedicated document HNSW index. - Query routing & retrieval: User queries are embedded on-the-fly and matched against the spatial graph. The greedy multi-layer search converges to the top candidate chunks within microseconds.
- Grounded prompt assembly: Retrieved context chunks are assembled into an evidence prompt with strict negative constraints instructing the model to refrain from hallucinating outside the retrieved sources.
- Token streaming: The local language model (
llama3.2) streams generated tokens back through Server-Sent Events (SSE) for a responsive typewriter interface. - Dimensionality projection: High-dimensional vectors are centered, decomposed into eigenvectors, and projected onto the principal axes for instant visualization.
System architecture
VECTORFORGE AI is designed around a clean domain-driven architecture:
- API & Controller layer: Spring Boot 3.5 REST controllers with virtual threads (
spring.threads.virtual.enabled=true) handling asynchronous requests and SSE streaming. - Service layer: Dedicated services for document chunking, RAG orchestration, synthetic benchmarking, and PCA linear algebra.
- Vector Database core: Authoritative vector repository with lazy cache invalidation. Indexes are derived structures keyed by algorithm and metric, rebuilt on demand upon data mutation.
- Local inference tier: High-throughput HTTP client utilizing JDK 21
HttpClientcommunicating with the local Ollama daemon over HTTP/NDJSON. - Frontend client: React 19 Single Page Application styled with a dark terminal aesthetic, interactive HTML5 canvas scatter plots, and keyboard shortcuts (
Cmd+1toCmd+5).
Tech stack
- Java 21 & Spring Boot 3.5: Core backend runtime, virtual threads, validation, and REST controllers.
- React 19 & Vite: Modern interactive web frontend with hot-reload development and optimized static builds.
- Custom Vector Engine: Scratch-built HNSW graph, KD-Tree partitioning, and Brute Force search algorithms.
- Ollama (
nomic-embed-text&llama3.2): 100% local embedding generation and LLM text generation. - Linear Algebra & PCA: Custom covariance matrix calculation and cyclic Jacobi eigensolver.
- JUnit 5 & MockMvc: 94 comprehensive automated tests covering mathematical proofs, algorithmic correctness, and HTTP contracts.
Engineering challenges
Exact KD-Tree pruning under Cosine Distance
KD-Trees partition space along coordinate axes, but cosine distance is non-metric and angular—meaning coordinate clamping cannot directly compute distance to a bounding box. To solve this, VECTORFORGE AI maps vectors onto the Euclidean hypersphere where cosine distance corresponds to half the squared Euclidean distance between unit vectors. The tree operates in normalized space with coordinate-clamped lower bounds, guaranteeing zero false pruning.
High-dimensional degradation
During synthetic benchmarking, testing revealed that while KD-Tree pruning excels in low-dimensional space (2D to 4D), it degenerates toward brute-force complexity as dimensionality increases (d >= 16). Because distances between points concentrate in higher dimensions, queries sit near bounding box boundaries, forcing the search to visit 70% to 80% of branches. This empirical demonstration visually proves why graph-based indexes like HNSW are necessary for modern high-dimensional embeddings.